Drowning in Signal: Why Richer Observability Data Is Making Hybrid IT Decisions Harder
For years, the dominant complaint in enterprise IT operations was that there was not enough data. Systems produced logs that were never collected, metrics that were never aggregated, and events that were never correlated. The answer, delivered over the past decade by a generation of sophisticated observability platforms, was instrumentation at scale. Collect everything. Store everything. Surface everything.
The complaint has changed. The new problem is not scarcity. It is volume.
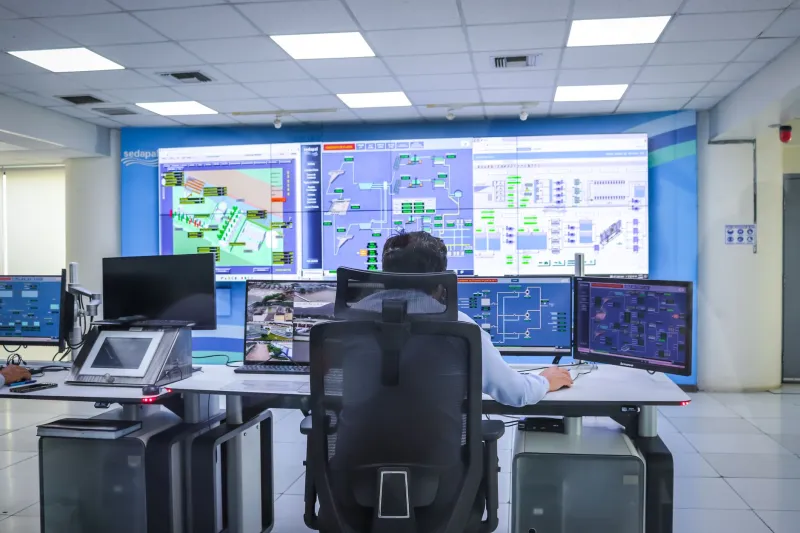
Enterprise hybrid environments now generate telemetry at a rate that would have been unimaginable to the operations teams of a prior generation. Distributed tracing, continuous profiling, infrastructure metrics, application performance data, security event streams, and synthetic monitoring outputs converge in dashboards of formidable complexity. The tools have delivered on their technical promise. What they have not delivered is clarity.
For a significant number of enterprise IT organizations, the observability stack has become a source of cognitive overhead rather than operational confidence. Alerts fire constantly. Dashboards accumulate panels that nobody examines. Engineers develop a learned skepticism toward monitoring outputs that, in the most problematic cases, causes them to discount warnings that actually matter. The system designed to make infrastructure behavior visible has made it, paradoxically, harder to see.
The Anatomy of Alert Fatigue
Alert fatigue is not a new concept, but its dynamics in hybrid environments deserve specific examination. In traditional on-premises monitoring, alert volumes were naturally constrained by the relatively modest number of discrete systems under observation. A data center with 200 servers and a fixed set of network appliances generates a bounded alert space. Thresholds could be tuned, escalation paths could be defined, and on-call engineers could develop reliable intuitions about which alert categories required immediate attention.
Hybrid environments dissolve those natural constraints. Cloud-native workloads are ephemeral by design—containers spin up and down continuously, serverless functions execute in milliseconds, autoscaling groups expand and contract in response to load. Each of these events can generate monitoring signals. The volume of alerts associated with normal, healthy hybrid infrastructure operation can easily reach levels that would have indicated a serious incident in a traditional data center context.
The consequence is a calibration failure. Alert thresholds that were appropriate for static infrastructure become meaningless in dynamic environments. Engineers who cannot distinguish between alerts representing genuine anomalies and alerts representing expected infrastructure behavior will eventually stop trusting the alert system at all. When that trust breaks down, the observability investment stops producing value—and the organization is, in a meaningful sense, flying blind even while staring at a full dashboard.
What Most Observability Strategies Get Wrong
The instinct driving most enterprise observability programs is essentially additive. New systems get instrumented. New metrics get defined. New dashboards get built. The portfolio of monitored signals expands over time without a corresponding discipline around what should be removed or deprioritized.
This reflects a reasonable concern: if a metric is not being collected, it cannot be analyzed during a post-incident review. The fear of missing a critical signal drives teams toward comprehensive collection even when they lack the capacity to act on that data meaningfully. The result is an observability estate that is technically complete and operationally unwieldy.
The more productive framing is not what should we monitor, but what data actually changes our decisions. These are not the same question. Many of the metrics flowing through enterprise observability platforms inform nobody's decision-making in practice. They are collected because collection is easy, not because the data has demonstrated analytical value. Treating collection as costless—in terms of engineering attention, alert volume, and cognitive load—is the foundational error.
Establishing Signal Discipline
The organizations that have navigated this challenge most effectively share a common reorientation: they approach observability as a product with defined consumers and defined use cases, rather than as an infrastructure service with open-ended scope.
This begins with a deliberate exercise in working backward from decisions. What are the operational decisions that the monitoring system is supposed to support? For each decision, what is the minimum data required to make it reliably? The answers to these questions define a core signal set—the metrics, events, and traces that have a direct line to operational action. Everything outside that set is a candidate for deprioritization, even if it is technically interesting.
Tiered alerting is a structural mechanism that supports this discipline. Not all alerts warrant the same response urgency, and conflating them—routing everything to the same on-call channel at the same priority level—is a primary driver of alert fatigue. A well-designed tiered model distinguishes between conditions requiring immediate human intervention, conditions that should be logged for next-business-day review, and conditions that should inform automated remediation without human involvement at all. The cognitive load on on-call engineers drops substantially when they can trust that the alerts reaching them have been filtered for genuine urgency.
Service level objectives provide another anchor for signal discipline. When observability strategy is organized around the SLOs that actually matter to the business—availability targets, latency thresholds, error rate tolerances—it becomes easier to evaluate the relevance of any given metric. If a metric does not contribute to assessing or predicting SLO compliance, its priority in the observability stack can be reduced accordingly.
The Organizational Dimension of Observability Debt
Technical solutions address only part of this problem. The accumulation of low-value signals in enterprise observability estates is also an organizational phenomenon. Dashboards built for specific projects persist indefinitely after those projects close. Alert rules authored by engineers who have since left the organization remain active without anyone reviewing their continued relevance. Instrumentation added during an incident investigation never gets removed once the incident is resolved.
Addressing this requires deliberate governance: periodic reviews of the active alert catalog, ownership assignments for dashboard maintenance, and a deprecation process for monitoring artifacts that no longer serve a defined purpose. These practices are unglamorous and rarely prioritized, but their absence is a significant contributor to the signal-to-noise problem.
Leadership has a role to play in establishing the organizational norm that observability quality matters as much as observability coverage. When engineering leaders ask not only whether a system is instrumented but whether the instrumentation is generating actionable intelligence, they create an incentive structure that rewards signal discipline rather than signal volume.
Toward Observability That Accelerates Rather Than Impedes
The maturity of an enterprise's observability practice is not measured by the number of metrics it collects or the sophistication of its dashboards. It is measured by the speed and confidence with which its teams make operational decisions.
Organizations that have achieved genuine observability maturity tend to share certain characteristics. Their on-call engineers trust their alert systems because those systems have been tuned to surface real problems and suppress ambient noise. Their dashboards tell coherent operational stories rather than presenting undifferentiated data. Their incident response times reflect the clarity of their monitoring outputs, not the volume.
Getting there requires a willingness to treat reduction as a form of progress—to recognize that removing a low-value alert or deprecating an unused dashboard is a meaningful improvement to the operational environment. In hybrid IT, where complexity is a permanent condition rather than a temporary phase, the organizations that manage signal discipline most rigorously will consistently outperform those that confuse more data with better insight.